This page introduces random walks on graphs from the perspectives of grid graphs, sparse graphs, and general graphs, presenting several solution methods and comparing their advantages and disadvantages.
Definition
Given a simple directed graph and start vertex , terminal vertex , let every edge have a positive weight satisfying , . Also, assume that for every vertex there is a path from to . A token starts from the start vertex and, each second, from its current vertex , with probability , chooses an outgoing edge and moves to . It stops on reaching the terminal vertex. Find the expected time taken.
In fact, this problem can also be written in matrix form. Define the matrix by:
The required answer is:
Here, is the probability of first reaching the terminal vertex after steps. When the graph is finite and every vertex can reach the terminal vertex, the definition of shows that all its eigenvalues are less than one, so the answer is guaranteed to converge.
For convenience, unless otherwise specified, this page uses to denote and to denote .
In addition, a sparse graph on this page means a graph whose numbers of edges and vertices are of the same order.
Grid graphs
Example 1: Circles of Waiting
A token starts at the point in the Cartesian plane and moves randomly every second. If it is currently at , then in the next second it moves with probability to , with probability to , with probability to , and with probability to . It is guaranteed that . Find the expected time until it moves to a position whose Euclidean distance from the origin is greater than . , , and the answer is taken modulo .
Naive approach
Let denote the expected time, starting from , to reach a position whose Euclidean distance from the origin is greater than . The recurrence is:
Because the transitions do not have a topological order, Gaussian elimination is required. The time complexity is , which is too high for this problem.
Direct elimination
Notice that most coefficients in the equations to be eliminated are zero. The complexity can be reduced by computing only positions with nonzero values during elimination.
Consider the elimination process. Eliminate the equations from top to bottom in the coordinate system, and from left to right within each row. Color eliminated equations yellow, points adjacent to yellow points green, and all other points black, as shown below:
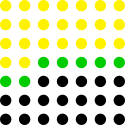
Next, eliminate the equation corresponding to the next green cell. In this equation, only the coefficients of the variables corresponding to the green cell and the first black cell below it may be nonzero; likewise, only the equations corresponding to those two cells may have a nonzero coefficient for the variable corresponding to the current cell.
There are only green cells, so eliminating one equation takes time. Since there are only equations, the total time complexity is reduced to , which is sufficient for this problem.
Pivot method
There are equations and variables. If the size can be reduced to , naive Gaussian elimination will be sufficient.
Take the variable corresponding to the leftmost cell in each row as a pivot; there are pivots in total. Express the variables corresponding to all other cells as linear functions of these pivots. Consider the columns from left to right. For each cell in the current column, are known linear functions of the pivots. Rearranging the recurrence gives:
This gives a linear-function representation of in terms of the pivots. If is already at Euclidean distance greater than from the origin, we obtain the equation . In the end, there are equations, on which we can perform Gaussian elimination.
During the stage of recursively deriving the linear functions of the pivots, there are variables and deriving each variable takes time; afterward, the problem size has been reduced to . Both parts take time, so the total time complexity is also , which is sufficient for this problem.
Comparison of the two approaches
The two approaches are compared below from several perspectives:
In terms of time complexity, the worst-case complexity of the pivot method on a grid graph is (it is highest when both the length and width of the grid graph are of order ), while the worst-case complexity of direct elimination is . The pivot method is better.
In terms of precision, direct elimination is more accurate than the pivot method for problems requiring real-number calculations rather than calculations modulo a number.
In terms of applicability, the two approaches are suited to different situations.
When the grid graph contains obstacles or some edges have probability , the pivot method needs one additional pivot for every obstacle or edge with probability . When the number of obstacles or edges with probability exceeds , the time complexity of the pivot method increases, while the time complexity of direct elimination remains unchanged.
However, the pivot method can also eliminate recurrences similar to those on grid graphs, such as , where is given by the problem. The complexity analysis for direct elimination does not apply to this model.
In addition, the determinant of a grid graph's adjacency matrix cannot be computed with the pivot method; only direct elimination can optimize its time complexity.
In summary, each approach has its strengths, and the appropriate one should be chosen after analyzing the specific problem.
Sparse graphs
Example 2: Expected Value
Given a simple, undirected, connected sparse graph , a token starts at . Each second it chooses uniformly among the edges incident to its current vertex and moves to the vertex at the other end. Find the expected time to reach . , and the answer is taken modulo , where is a randomly generated prime in the interval .
Prerequisites
Definition 4.1. Every polynomial satisfying , namely , is called an annihilating polynomial of matrix .
Definition 4.2. Let denote the -th order identity matrix. The characteristic polynomial of an matrix is defined as , where denotes the determinant of a matrix. It is easy to see that the characteristic polynomial of an -th order matrix has degree at most .
Theorem 4.2. (Cayley–Hamilton theorem) The characteristic polynomial of any matrix is an annihilating polynomial for that matrix.
Therefore, the degree of the annihilating polynomial of least degree for an -th order matrix is also at most .
Solving the original problem
Notice that the expected time is the sum of the probabilities that the walk has not ended after steps. If we can find these probabilities, summing over all gives the answer.
Let denote the probability that after steps the token is currently at and has never reached . Then:
Here denotes the degree of .
The transition of is independent of , so one transition can be viewed as multiplication by a matrix, namely . Since the least-degree annihilating polynomial of has degree at most , the shortest recurrence for also has length at most . Therefore, the shortest recurrence for also has length at most . We can, in time, compute ; then, in time, use the Berlekamp–Massey algorithm to find the shortest recurrence for .
Consider a -th order linear recurrence sequence . Suppose that for , . Let the generating functions of and be and , respectively. Then , where is determined by the terms with .
Returning to the original problem, once we know the shortest recurrence for , we can find and (with the same definitions as in the preceding paragraph). Rearranging gives . We seek , which is clearly . Substituting solves the original problem. Since the modulus is a random prime, we may assume the denominator is not .
Thus, the problem is solved in time. If the numbers of vertices and edges of are of the same order, the time complexity here can be regarded as .
General graphs
Example 3: Frank
Given a simple strongly connected directed graph , for all , , and , answer the following question: A token starts at . Each second it chooses uniformly among the outgoing edges of its current vertex and moves to the vertex at the other end. Find the expected time to reach . .
Analysis and transformation
Let be the probability, when the token is at , of choosing the outgoing edge and moving to ; in particular, it is when the edge does not exist. Let be the expected time for a random walk from to ; in particular, . When , the recurrence is:
When , let denote the expected time for a random walk starting at to return to for the first time. Then:
For clarity, write the recurrence in matrix form. Let be the transition matrix of the graph, the answer matrix, the -th order identity matrix, the all-ones -th order matrix with entries , and an -th order matrix satisfying and having elsewhere. Then:
If we can find , we only need to solve:
Finding G
Definition 5.1. The stationary distribution of an -th order transition matrix is an -dimensional vector satisfying and . Every component of lies in the interval .
The meaning of a stationary distribution is easy to see. If at some moment the token has probability of being at , then it has the same distribution at every later moment. We can, in time, find by solving a system with Gaussian elimination. What is the relationship between and ?
Theorem 5.1. For every , .
Proof
From , rearranging gives:
Multiplying both sides on the left by gives:
By the definition of , we have , so:
Therefore:
This proves the original proposition.
Thus, by introducing the stationary distribution, in time we can find .
Solving the original problem
While solving the system, we encounter a problem: is rank-deficient, so the system cannot be solved by multiplying by an inverse matrix.
Definition 5.2. A directed spanning tree of rooted at is a subgraph of , namely , satisfying:
- For every , the out-degree of is .
- The out-degree of is .
- contains no cycles.
Lemma 5.1. (The directed matrix-tree theorem) For a directed graph , let be its out-degree matrix, namely and , where is the out-degree of , and let be its adjacency matrix. The number of directed spanning trees rooted at is the determinant of with row and column deleted.
Theorem 5.2. For a strongly connected graph and its transition matrix , the rank of is .
Proof
Multiplying a row of a matrix by a nonzero constant does not change its rank, so, for , multiply row by the out-degree of to obtain a new matrix . It suffices to prove that the rank of is .
Since every row of sums to , summing all column vectors of gives the zero vector, so these vectors are linearly dependent.
so the rank of is not .
It is easy to see that equals the out-degree matrix of graph minus its adjacency matrix. By Lemma 5.1, with row and column deleted
yields a determinant equal to the number of directed spanning trees rooted at .
Since G is strongly connected, the number of directed spanning trees rooted at any vertex is nonzero, namely not . Thus, after deleting 's row
and column , the matrix remains full rank.
Since adding a column cannot decrease rank, with row deleted has linearly independent row vectors. Hence the rank of is .
Return to the original problem and consider solving its system. For convenience, write it as ,
where and are known and is unknown. Since is rank-deficient, there are infinitely many solutions; first find one particular solution.
Perform Gaussian elimination on and together. Reduce by eliminating its first rows so that only the main diagonal and the -th column can have nonzero entries,
and reduce the last row to all , obtaining the following form:
Set to obtain a particular solution, denoted by . Next adjust this particular solution to obtain an actual solution.
Since , the combinatorial interpretation gives . It is easy to solve for .
This solves the problem in time.
References
- A brief discussion of random walks on graph models. IOI2019 Chinese National Team Candidate Collection of Papers (pp. 17–26)